
MixtureModelClassifier#
- class skactiveml.classifier.MixtureModelClassifier(mixture_model=None, weight_mode='responsibilities', classes=None, missing_label=nan, cost_matrix=None, class_prior=0.0, random_state=None, target_type='auto')[source]#
Bases:
ClassFrequencyEstimatorClassifier based on a Mixture Model (CMM)
The classifier based on a mixture model (CMM) is a generative classifier based on a (Bayesian) Gaussian mixture model (GMM).
- Parameters:
- mixture_modelsklearn.mixture.GaussianMixture or sklearn.mixture.BayesianGaussianMixture or None, default=None
(Bayesian) Gaussian Mixture model that is trained with unsupervised algorithm on train data. If the initial mixture model is not fitted, it will be refitted in each call of the fit method. If None, mixture_model=BayesianGaussianMixture(n_components=n_classes) will be used. Multi-label classification requires an explicit mixture model, because the number of label outputs does not define the number of mixture components.
- weight_mode‘responsibilities’ or ‘similarities’, default=’responsibilities’
Determines whether the responsibilities outputted by the mixture_model or the exponential of the Mahalanobis distances as similarities are used to compute the class frequency estimates.
- classesarray-like of shape (n_classes,) or a list of array-like of shape (2,), default=None
Holds the label for each class. Nested binary vocabularies describe one vocabulary per output for multi-label classification. If None, the classes are determined during the fit.
- missing_labelscalar or str or np.nan or None, default=np.nan
Value to represent a missing label.
- cost_matrixarray-like, shape (n_classes, n_classes)
Cost matrix with cost_matrix[i,j] indicating cost of predicting class classes[j] for a sample of class classes[i]. Can be only set, if classes is not None.
- class_priorfloat or array-like of shape (n_classes,) or (n_outputs, 2), default=0
Prior observations of the class frequency estimates. If class_prior is an array for single-output classification, class_prior[i] indicates the non-negative prior number of samples belonging to class classes_[i]. For multi-label classification, an array contains one binary prior per output. If class_prior is a float, it indicates the non-negative prior number of samples per class for every output.
- random_stateint or RandomState instance or None, default=None
Determines random number for predict method. Pass an int for reproducible results across multiple method calls.
- target_type“auto” or “single-output” or “multi-label”, default=”auto”
Declared target type. This estimator supports single-output and multi-label classification.
- Attributes:
- classes_np.ndarray of shape (n_classes,) or list of np.ndarray
Holds the label for each class after fitting.
- class_prior_np.ndarray of shape (n_classes,) or (n_outputs, 2)
Prior observations of the class frequency estimates, ordered like classes_ for single-output targets and like each output’s canonical binary vocabulary for multi-label targets.
- cost_matrix_np.ndarray, shape (classes, classes)
Cost matrix with cost_matrix_[i,j] indicating cost of predicting class classes_[j] for a sample of class classes_[i].
- F_components_numpy.ndarray of shape (n_components, n_classes) or (n_components, n_outputs, 2)
For single-output targets, F_components_[j, c] is a proxy for the number of samples of class c belonging to component j. For multi-label targets, the final two axes identify the output and its canonical binary class.
- mixture_model_sklearn.mixture.GaussianMixture or sklearn.mixture.BayesianGaussianMixture
(Bayesian) Gaussian Mixture model that is trained with unsupervised algorithm on train data.
Methods
fit(X, y[, sample_weight])Fit the model using X as samples and y as class labels.
predict(X, **kwargs)Return class label predictions for the test samples X.
predict_freq(X)Return class frequency estimates for the input data X.
predict_proba(X, **kwargs)Return probability estimates for the test data X.
sample_proba(X[, n_samples, random_state])Samples probability vectors from Dirichlet distributions whose parameters alphas are defined as the sum of the frequency estimates returned by predict_freq and the class_prior.
score(X, y[, sample_weight])Return the mean accuracy on the given test data and labels.
Get metadata routing of this object.
get_params([deep])Get parameters for this estimator.
set_fit_request(*[, sample_weight])Configure whether metadata should be requested to be passed to the
fitmethod.set_params(**params)Set the parameters of this estimator.
set_score_request(*[, sample_weight])Configure whether metadata should be requested to be passed to the
scoremethod.
- MixtureModelClassifier.fit(X, y, sample_weight=None)[source]#
Fit the model using X as samples and y as class labels.
- Parameters:
- Xarray-like of shape (n_samples, n_features)
The feature matrix representing the samples.
- yarray-like of shape (n_samples,) or (n_samples, n_outputs)
It contains the class labels of the training samples.
- sample_weightarray-like of shape (n_samples,) or (n_samples, n_outputs)
It contains the weights of the training samples’ class labels. One weight per sample or one weight per target entry can be provided.
- Returns:
- self: skactiveml.classifier.MixtureModelClassifier
The MixtureModelClassifier fitted on the training data.
- MixtureModelClassifier.predict(X, **kwargs)#
Return class label predictions for the test samples X.
- Parameters:
- Xarray-like of shape (n_samples, …)
Input samples.
- Returns:
- ynumpy.ndarray of shape (n_samples,)
Predicted class labels of the test samples X.
- MixtureModelClassifier.predict_freq(X)[source]#
Return class frequency estimates for the input data X.
- Parameters:
- Xarray-like of shape (n_samples, n_features)
Input samples.
- Returns:
- Fnp.ndarray of shape (n_samples, n_classes) or (n_samples, n_outputs, 2)
The class frequency estimates of the input samples. Classes are ordered according to the attribute classes_.
- MixtureModelClassifier.predict_proba(X, **kwargs)#
Return probability estimates for the test data X.
- Parameters:
- Xarray-like of shape (n_samples, n_features)
Input samples.
- Returns:
- Parray-like of shape (n_samples, n_classes) or (n_samples, n_outputs)
The class probabilities of the test samples. For multi-label targets, each entry is the probability of the second class in the corresponding canonical binary class vocabulary. An output with zero estimated frequencies and zero prior has probability 0.5.
- MixtureModelClassifier.sample_proba(X, n_samples=10, random_state=None)#
Samples probability vectors from Dirichlet distributions whose parameters alphas are defined as the sum of the frequency estimates returned by predict_freq and the class_prior.
- Parameters:
- Xarray-like of shape (n_test_samples, n_features)
Test samples for which n_samples probability vectors are to be sampled.
- n_samplesint, default=10
Number of probability vectors to sample for each X[i].
- random_stateint or numpy.random.RandomState or None, default=None
Ensure reproducibility when sampling probability vectors from the Dirichlet distributions.
- Returns:
- Parray-like of shape (n_samples, n_test_samples, n_classes) or (n_samples, n_test_samples, n_outputs, 2)
There are n_samples class probability vectors for each test sample in X. For multi-label targets, the final axis follows each output’s canonical binary class vocabulary.
- Raises:
- ValueError
If any class has zero frequency observations after adding the prior. Set a positive class_prior to make every Dirichlet parameter positive.
- MixtureModelClassifier.score(X, y, sample_weight=None)#
Return the mean accuracy on the given test data and labels.
- Parameters:
- Xarray-like of shape (n_samples, …)
Test samples.
- yarray-like of shape (n_samples,)
True class labels of the test samples X.
- sample_weightarray-like of shape (n_samples,), default=None
Sample weights of the test sample X.
- Returns:
- scorefloat
Mean accuracy of self.predict(X) regarding y.
- MixtureModelClassifier.get_metadata_routing()#
Get metadata routing of this object.
Please check User Guide on how the routing mechanism works.
- Returns:
- routingMetadataRequest
A
MetadataRequestencapsulating routing information.
- MixtureModelClassifier.get_params(deep=True)#
Get parameters for this estimator.
- Parameters:
- deepbool, default=True
If True, will return the parameters for this estimator and contained subobjects that are estimators.
- Returns:
- paramsdict
Parameter names mapped to their values.
- MixtureModelClassifier.set_fit_request(*, sample_weight: bool | None | str = '$UNCHANGED$') MixtureModelClassifier#
Configure whether metadata should be requested to be passed to the
fitmethod.Note that this method is only relevant when this estimator is used as a sub-estimator within a meta-estimator and metadata routing is enabled with
enable_metadata_routing=True(seesklearn.set_config()). Please check the User Guide on how the routing mechanism works.The options for each parameter are:
True: metadata is requested, and passed tofitif provided. The request is ignored if metadata is not provided.False: metadata is not requested and the meta-estimator will not pass it tofit.None: metadata is not requested, and the meta-estimator will raise an error if the user provides it.str: metadata should be passed to the meta-estimator with this given alias instead of the original name.
The default (
sklearn.utils.metadata_routing.UNCHANGED) retains the existing request. This allows you to change the request for some parameters and not others.Added in version 1.3.
- Parameters:
- sample_weightstr, True, False, or None, default=sklearn.utils.metadata_routing.UNCHANGED
Metadata routing for
sample_weightparameter infit.
- Returns:
- selfobject
The updated object.
- MixtureModelClassifier.set_params(**params)#
Set the parameters of this estimator.
The method works on simple estimators as well as on nested objects (such as
Pipeline). The latter have parameters of the form<component>__<parameter>so that it’s possible to update each component of a nested object.- Parameters:
- **paramsdict
Estimator parameters.
- Returns:
- selfestimator instance
Estimator instance.
- MixtureModelClassifier.set_score_request(*, sample_weight: bool | None | str = '$UNCHANGED$') MixtureModelClassifier#
Configure whether metadata should be requested to be passed to the
scoremethod.Note that this method is only relevant when this estimator is used as a sub-estimator within a meta-estimator and metadata routing is enabled with
enable_metadata_routing=True(seesklearn.set_config()). Please check the User Guide on how the routing mechanism works.The options for each parameter are:
True: metadata is requested, and passed toscoreif provided. The request is ignored if metadata is not provided.False: metadata is not requested and the meta-estimator will not pass it toscore.None: metadata is not requested, and the meta-estimator will raise an error if the user provides it.str: metadata should be passed to the meta-estimator with this given alias instead of the original name.
The default (
sklearn.utils.metadata_routing.UNCHANGED) retains the existing request. This allows you to change the request for some parameters and not others.Added in version 1.3.
- Parameters:
- sample_weightstr, True, False, or None, default=sklearn.utils.metadata_routing.UNCHANGED
Metadata routing for
sample_weightparameter inscore.
- Returns:
- selfobject
The updated object.
Examples using skactiveml.classifier.MixtureModelClassifier#
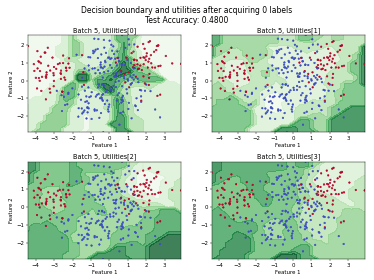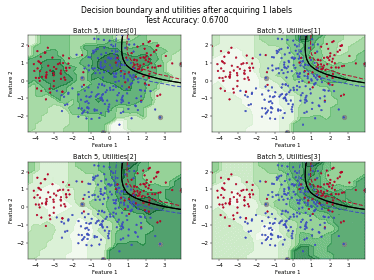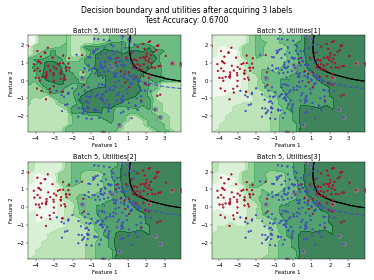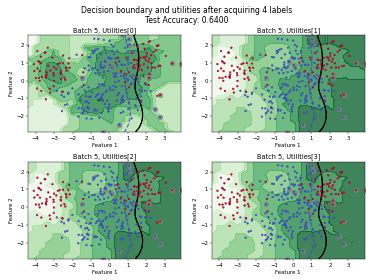
Batch Density-Diversity-Distribution-Distance Sampling (4DS)
Density-Diversity-Distribution-Distance Sampling (4DS)